The Fine-Tuning Fallacy: When to Prompt, Retrieve, or Train Your Model
If you hang around AI engineering forums long enough, you notice a pattern: a team builds an LLM feature, runs into accuracy or formatting issues, and immediately decides they need to fine-tune a model.
Fine-tuning feels like the “real” engineering solution. It sounds rigorous, bespoke, and sophisticated. But in practice, reaching for fine-tuning as your first tool often leads to wasted training compute, brittle deployments, and unnecessary maintenance overhead.
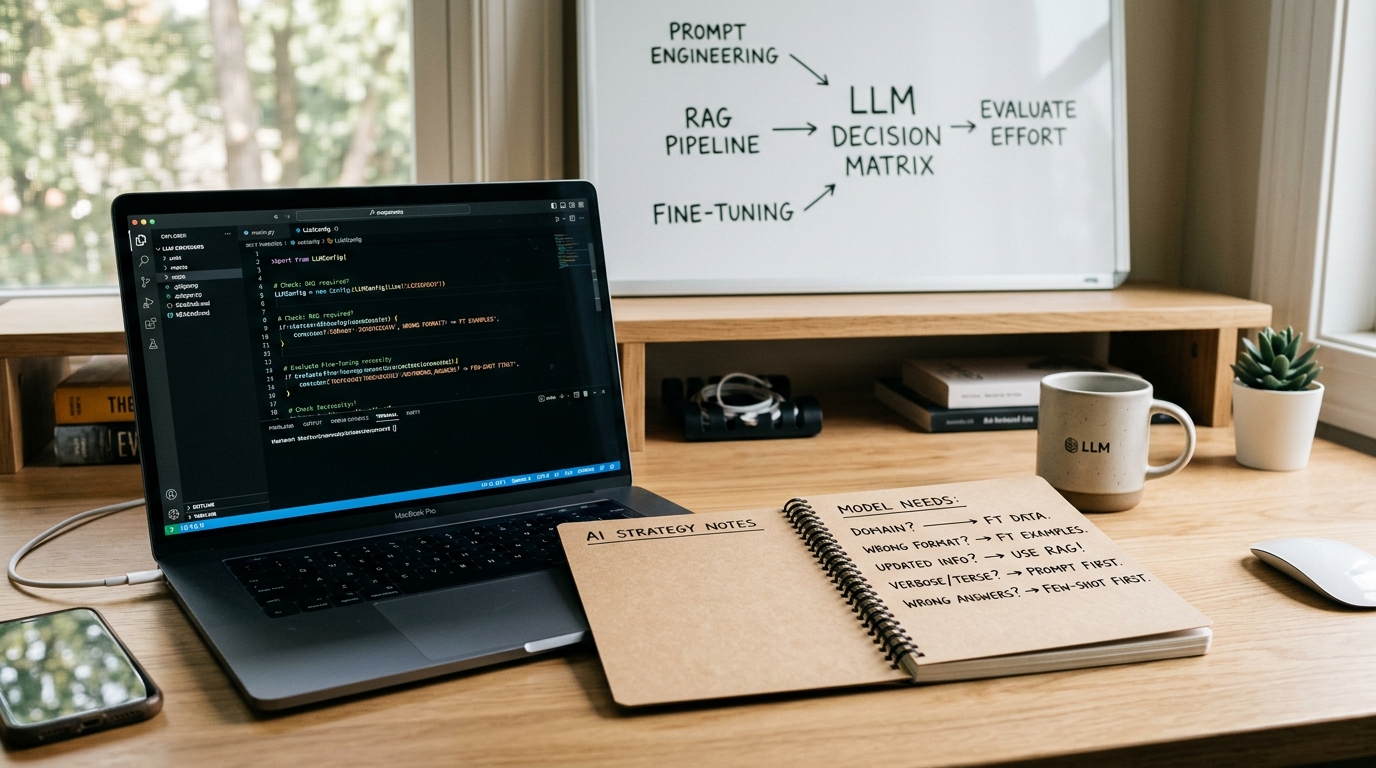
A post over on gemma4-ai.com lays out a rough decision matrix along these lines:
| Situation | Solution |
|---|---|
| Model doesn’t know your domain | Fine-tune with domain data |
| Model ignores your output format | Fine-tune with format examples |
| Model needs updated info | Use RAG instead |
| Model is too verbose/terse | Try prompt engineering first |
| Model gives wrong answers sometimes | Try few-shot prompting first |
That table is a reasonable starting intuition - fine-tuning should usually be an escalation step, not your default starting point - but it’s a five-row simplification of a much messier decision. The rest of this post is about the nuance it leaves out, and about using evaluation data rather than a lookup table to make the call.
1. Style vs. factuality: what fine-tuning actually does well
The biggest mistake teams make is trying to treat model weights as a dynamic relational database.
Fine-tuning modifies the internal probabilistic biases of a model. It is exceptional at adapting behavior, output style, specialized syntax, and domain reasoning patterns. If you need a model to consistently adopt a strict legal tone, speak fluent internal jargon, or follow complex multi-step reasoning steps unique to your industry, fine-tuning works well.
Where fine-tuning becomes a poor fit is storing fluid, verifiable factual knowledge.
If your domain knowledge changes regularly (e.g., product inventory, customer records, company policy docs), embedding those facts into model weights creates three massive headaches:
- No provenance: You can’t ask weights to cite the specific page or document version it used to generate an answer.
- Update friction: You can’t run a SQL query or drop a document to update a weight; you have to run a full training job.
- Hallucination risk: Fine-tuned models present stale parametric knowledge with high confidence.
The fix: If the core challenge is keeping facts fresh, accurate, and inspectable, Retrieval-Augmented Generation (RAG) is the right architectural fit. Fine-tuning should be reserved for shaping how the model reasons about or presents that knowledge, not how it remembers it.
2. Formatting issues: use native tooling before custom weights
It’s frustrating when a base model returns markdown wrapped around JSON, omits required keys, or invents a field that breaks your backend parser.
While fine-tuning on a dataset of formatted inputs and outputs will lock in syntax consistency, it’s often an over-engineered fix for modern APIs. Most major providers now offer native Structured Outputs (JSON Schema enforcement) and formal Tool Calling / Function Calling interfaces.
Before committing to training fine-tuned formatting models:
- Leverage Structured Output APIs: they enforce the output schema at decoding time, without training overhead.
- Reserve fine-tuning for optimization: If you are processing millions of high-throughput requests daily where long system prompts and JSON schemas add significant token latency and cost, fine-tuning a smaller base model to output strict schemas natively becomes a valid ROI win.
3. Don’t skip few-shot prompting
When a model gives incorrect answers on edge cases, the natural reaction is to think, “It needs more training data.”
In reality, base instruction-tuned models are capable of complex reasoning if you show them what success looks like. Adding 3 to 5 realistic input-and-output pairs directly into the prompt (few-shot prompting) can resolve many reasoning failures.
System Prompt:
You extract key entity data from insurance claims. Follow these examples:

Input: "Claim #402. Water damage in kitchen on 12/04. Estimate pending."
Output: {"claim_id": 402, "type": "water", "status": "pending"}

Input: "Claim #901. Auto collision on I-95. Denied due to policy lapse."
Output: {"claim_id": 901, "type": "auto", "status": "denied"}
However, few-shot prompting isn’t magic. If an underlying base model fundamentally lacks the reasoning capability for a specialized task, or if context window costs explode from pasting dozens of examples, that is your signal to transition toward fine-tuning.
4. The hidden overhead of fine-tuning
Before moving from prompting or RAG to a custom fine-tuning pipeline, account for the long-term operational tax:
- Task regression: Fine-tuning on a narrow dataset can cause performance regressions on general instruction-following or adjacent tasks. Regular evaluation against base model benchmarks is necessary.
- Model lifecycle coupling: When you fine-tune, you tie your pipeline to a specific base model checkpoint. When base model providers release newer, cheaper, or faster models, you can’t simply change a model string parameter; you have to curate your dataset and retrain from scratch.
- Data curation costs: Preparing high-quality fine-tuning pairs (often requiring hundreds or thousands of clean, curated records) takes significantly more time than writing prompt examples.
The core rule: let evaluation guide your architecture
Instead of picking a path off a lookup table, run an evaluation-first workflow and let the failures tell you what’s actually missing:
[Define Test Cases] -> [Build Eval Set] -> [Prompt Baseline] -> [Measure Score]
                                                                     |
                     +-----------------------------------------------+-----------------------------------------------+
                     |                                                                                                 |
          [Passes Accuracy / Latency]                                                                        [Fails Criteria]
                     |                                                                                                 |
              (Ship to Prod)                                              +--------------------------------+--------------------------------+
                                                                           |                                 |                                |
                                                          [Needs Fresh/External Knowledge]      [Needs Task/Style Alignment]      [Needs Both]
                                                                           |                                 |                                |
                                                                   (Add RAG Pipeline)           (Fine-Tune Base Model)        (RAG + Fine-Tune)
- Build an evaluation set: Collect 50 to 100 realistic, hard input cases along with expected outputs.
- Start with zero-shot / few-shot prompts: Measure accuracy, token costs, and latency against your eval set.
- Layer in RAG: If failures are driven by missing, stale, or dynamic factual context, introduce retrieval.
- Escalate to fine-tuning: If failures stem from task complexity, unique domain style, or strict behavioral formatting requirements that prompt engineering can’t fix, build a dataset and train.
These two paths aren’t mutually exclusive. One of the more common production architectures is RAG plus fine-tuning together: retrieval supplies the fresh, citable knowledge, and fine-tuning teaches the model how to use and present that retrieved context in your house style.
Rather than guessing whether you need prompting, RAG, fine-tuning, or some combination, let your eval set decide. That’s the actual engineering discipline here - not “fine-tuning is overrated,” but “don’t skip the measurement step before reaching for the expensive one.”